Activation and Loss function implementations
Activation and Loss function implementations
Deep learning Functions
Functions in this notebook are created using low level math functions in pytorch. Then the functions are validated with preimplemented versions inside pytorch.
1
2
3
import torch
from torch import nn
import matplotlib.pyplot as pp
simple perceptron
1
2
3
4
5
6
class Perceptron(nn.Module):
    def __init__(self,in_size,out_size):
        super(Perceptron,self).__init__()
        self.linear = nn.Linear(in_size, out_size)
    def forward(self, x):
        return self.linear(x).squeeze()
1
2
3
4
5
6
7
8
9
10
11
model = Perceptron(1,1)
params =[p for p in model.parameters()]
x = torch.randn(1)
print('x = ',x)
y = model(x)

w,b = params[0].item(),params[1].item()
print('\nw = {}, b={}\n'.format(w,b))
print('y = ',y)

print('wx+b = ',w*x+b)
1
2
3
4
5
6
x =  tensor([-0.5909])

w = -0.36968421936035156, b=-0.5664300918579102

y =  tensor(-0.3480, grad_fn=<SqueezeBackward0>)
wx+b =  tensor([-0.3480])
Activation function
sigmoid
1
2
3
4
5
6
7
8
9
def plotfun(myfun, fun):
    x = torch.linspace(-5,5,20)

    y1 = myfun(x)
    y2 = fun(x)

    pp.plot(x.numpy(),y1.detach().numpy())
    pp.plot(x.numpy(),y2.detach().numpy(), 'o')
    pp.legend(['y1','y2'])
1
2
3
4
5
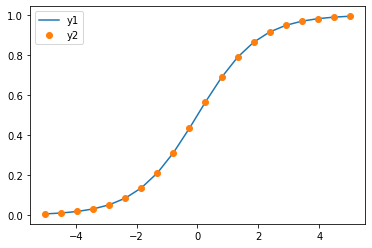
def mysigmoid(x):
    return 1/(1+torch.exp(-x))
sigmoid = torch.sigmoid

plotfun(mysigmoid, sigmoid)
tanh
1
2
3
4
5
6
7
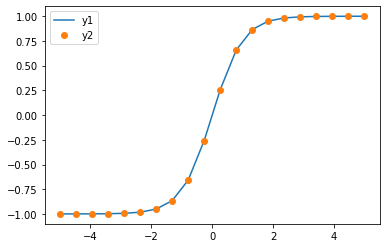
def mytanh(x):
    return (torch.exp(x)-torch.exp(-x))/(torch.exp(x)+torch.exp(-x))

tanh = torch.tanh


plotfun(mytanh, tanh)
relu
1
2
3
4
5
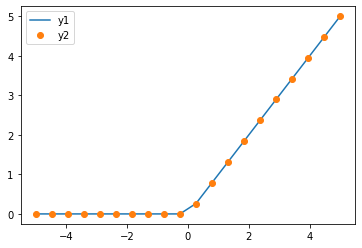
def myrelu(a):
    return (a>=0).float() *a
relu = torch.nn.ReLU()
plotfun(myrelu, relu)
prelu
1
2
3
4
5
6
7
8
9
10
11
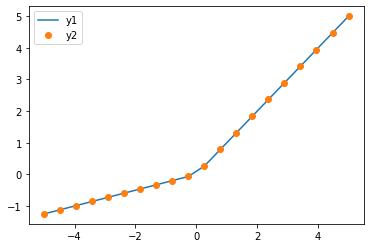
prelu = torch.nn.PReLU(1)
param = [p for p in prelu.parameters()][0]

def myprelu(param):
    def myprelu_int(x):
        y = x.clone()
        y[y<0] = param*y[y<0]
        return y
    return myprelu_int

plotfun(myprelu(param), prelu)
Softmax
1
2
3
4
5
6
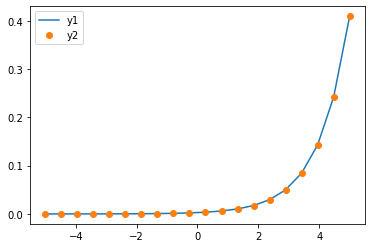
softmax = torch.nn.Softmax(0)
def mysoftmax(x):
    esum = torch.sum(torch.exp(x))
    return torch.exp(x)/ esum

plotfun(mysoftmax,softmax)
Loss Functions
MSE
1
2
3
4
5
6
7
8
def calculate_loss(myfun, fun,y,yhat):

    #pp.scatter(y.numpy(),yhat.detach().numpy())
    #pp.xlabel('y')
    #pp.ylabel('yhat')

    print('My Loss = ', myfun(yhat,y))
    print('pytorch Loss = ', fun(yhat,y))
1
2
3
4
5
6
7
8
y = torch.linspace(-5,5,20)
yhat = y + torch.randn_like(y) #noise

mse = nn.MSELoss()

def mymse(yhat,y):
    return torch.mean(torch.pow((yhat-y), 2)).squeeze()
calculate_loss(mymse,mse,y,yhat)
1
2
My Loss =  tensor(1.5757)
pytorch Loss =  tensor(1.5757)
Categorical crossentropy
Lcross_entropy(y,ŷ)=–∑yi log(ŷi)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
ce = nn.CrossEntropyLoss()

def myce(yhat,y):
    #convert to onehot
    y_new  = torch.zeros_like(yhat)
    for i, cat in enumerate(y):
        y_new[i][cat] = 1
    print(y_new)

    #do softmax normalization
    yhat = torch.nn.Softmax(dim = 1)(yhat)

    entropies = - torch.sum((y_new * torch.log(yhat)),1)
    print(entropies)

    return torch.mean(entropies).squeeze()

size = 5
classes = 3

y = torch.randint(0,3,(5,))
yhat = torch.randn(5,3)

print('y= ',y)
print('yhat = ',yhat)
calculate_loss(myce,ce,y,yhat)
1
2
3
4
5
6
7
8
9
10
11
12
13
14
y=  tensor([1, 0, 0, 0, 1])
yhat =  tensor([[-0.3912,  2.0449,  0.3688],
        [ 0.3825, -1.4309, -0.0162],
        [ 0.1920, -0.2347,  0.5387],
        [-1.7647,  0.8127, -0.5122],
        [-0.1184, -0.0798,  1.0779]])
tensor([[0., 1., 0.],
        [1., 0., 0.],
        [1., 0., 0.],
        [1., 0., 0.],
        [0., 1., 0.]])
tensor([0.2426, 0.6066, 1.1207, 2.8715, 1.6380])
My Loss =  tensor(1.2959)
pytorch Loss =  tensor(1.2959)
Binary Cross Entropy
1
2
3
4
5
6
7
8
9
10
11
bce = nn.BCELoss()

def mybce(yhat,y):
    return -1* torch.mean(y * torch.log(yhat) + (1-y) * torch.log(1-yhat))

y = torch.from_numpy(np.random.choice(2,(5,))).float()
yhat = torch.rand(5,)

print(y,yhat)

calculate_loss(mybce,bce, y, yhat)
1
2
3
tensor([0., 0., 0., 0., 1.]) tensor([0.4765, 0.3071, 0.1784, 0.3373, 0.8747])
My Loss =  tensor(0.3512)
pytorch Loss =  tensor(0.3512)
This post is licensed under CC BY 4.0 by the author.